How Large Language Models Like ChatGPT Generate Text
You type a question into ChatGPT and, within seconds, paragraphs begin appearing on the screen. The response might explain a scientific concept, rewrite an email, suggest a dinner recipe, analyze computer code, or create a story from scratch.
It can feel as though there must be a giant database somewhere containing the answer to every possible question.
That’s not how it works.
Large language models, or LLMs, generate text dynamically. At their core, they learn statistical patterns from enormous amounts of data and use those patterns to predict what should come next in a sequence.
That description sounds surprisingly simple considering what modern AI systems can do. The interesting part is what happens when prediction is performed by a neural network with enormous numbers of parameters, trained at massive scale and then further developed to follow instructions and solve useful tasks.
Here’s how the process actually works, without the complicated mathematics.
What Is a Large Language Model?
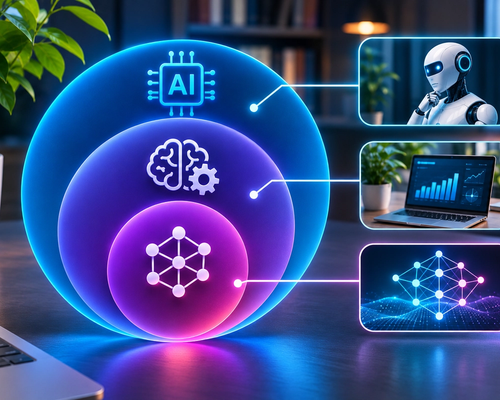
A large language model is a type of artificial intelligence designed to process and generate language.
The word large generally refers to the scale of the model, its training, and the resources involved. Modern language models can contain enormous numbers of parameters and can be trained using vast collections of text, code, images, and other forms of data, depending on the system.
The word language refers to the kinds of patterns these models learn to work with. They learn relationships among words, phrases, sentences, concepts, styles, and structures.
And model means that the system has learned a mathematical representation of patterns in its training data that it can use to make predictions.
An LLM doesn’t simply memorize a dictionary and a collection of facts. It learns complex relationships that allow it to generate new combinations of language.
It Starts With Training
Before an LLM can answer your questions, it has to be trained.
During training, the model processes enormous amounts of data and repeatedly practices predicting parts of that data from context.
Imagine giving a system the sentence:
She opened the umbrella because it started to…
A reasonable continuation would be rain.
At the beginning of training, a model may be terrible at making these predictions. It assigns probabilities poorly and makes many mistakes.
The training process measures those errors and adjusts the model’s internal parameters.
Then the model tries again.
And again.
And again.
This happens across enormous amounts of data.
Over time, the model becomes increasingly good at predicting language based on context.
What Exactly Does the Model Learn?
The model doesn’t learn only grammar.
To predict text well, it needs to learn many kinds of patterns simultaneously.
It learns that certain words commonly appear together. It learns sentence structure. It learns that questions are often followed by answers. It learns patterns associated with stories, instructions, arguments, computer code, conversations, summaries, explanations, and many other forms of communication.
Along the way, it can also learn relationships involving facts and concepts represented in its training data.
For example, correctly predicting language about Paris requires learning relationships between Paris, France, Europe, the Eiffel Tower, geography, travel, history, and many other concepts.
Nobody necessarily enters those relationships manually.
They emerge from learning patterns across huge numbers of examples.
The Model Doesn’t Read Words Exactly the Way You Do
Before text can be processed by a language model, it needs to be converted into units the model can work with.
These units are called tokens.
A token might represent an entire word, part of a word, punctuation, or another piece of text.
For example, a common word might be represented by one token, while an unusual or longer word could be divided into several tokens.
This matters because language models don’t literally see sentences as letters printed on a screen.
They receive numerical representations of tokens.
The model processes those representations through many layers of computation to understand how the tokens relate to one another in context.
Tokens Become Numbers
Computers don’t inherently understand the meaning of words such as “mountain,” “love,” or “computer.”
They work with numbers.
So each token is converted into a numerical representation, often called an embedding.
Embeddings allow the model to represent relationships among different pieces of language in a mathematical space.
Concepts used in similar contexts can develop representations that reflect some of those similarities.
For example, the model may learn relationships among concepts such as “king,” “queen,” “man,” and “woman,” or among “Paris,” “London,” “Rome,” and “city.”
These representations are far more complex than a simple dictionary definition.
They allow the model to process meaning through patterns of numerical relationships.
The Transformer Changed Language AI
Most modern large language models are based on a neural-network architecture called the transformer.
Transformers became particularly important because they’re good at processing relationships between different parts of a sequence.
Before transformers, language models often struggled more with long-range relationships in text.
A transformer can examine how different tokens relate to one another across a larger context.
One of the key mechanisms enabling this is called attention.
What Is Attention?
Attention allows the model to determine which parts of the available context are particularly relevant when processing another part.
Consider this sentence:
Maria put the cake in the refrigerator because it needed to stay cold.
To understand what “it” refers to, you need to connect it with “cake.”
Humans do this almost automatically.
A transformer uses attention mechanisms to calculate relationships among tokens and determine which parts of the context matter.
In real models, this happens across many attention patterns and many layers simultaneously.
The result is that the model can build increasingly sophisticated representations of the text it’s processing.
Then You Type a Prompt
After training, the model can be used to generate text.
Suppose you type:
Explain gravity to a ten-year-old.
Your prompt is broken into tokens and converted into numerical representations.
Those representations pass through the model.
The model considers the relationships among concepts such as “explain,” “gravity,” and “ten-year-old.” It also draws on patterns learned during training about scientific explanations, simple language, educational writing, and instruction following.
Then it calculates probabilities for what token should come next.
Maybe the response begins:
Gravity
The model then considers your original prompt plus the word it just generated and predicts the next token.
Perhaps:
is
Then it predicts again.
the
Then again.
force
This process continues until a complete response emerges.
The Answer Isn’t Written All at Once
One of the strangest things about language models is that the entire paragraph generally isn’t sitting somewhere waiting to be revealed.
It’s generated incrementally.
The model produces one token, then another, then another.
Each new token becomes part of the context used to predict what comes next.
This means the response develops as it is being generated.
If the model begins a sentence in one direction, those early choices influence what becomes likely later.
That’s part of why generative AI can produce responses that feel spontaneous.
The text is actually being generated.
Prediction Doesn’t Mean “Guessing Randomly”
Describing LLMs as prediction systems sometimes makes them sound like sophisticated autocomplete.
There is some truth to that comparison, but it can also be misleading.
The prediction being performed isn’t simply based on the previous two or three words.
Modern models can process large amounts of context and represent complex relationships involving concepts, instructions, structure, tone, and earlier parts of a conversation.
Suppose you ask:
Write a polite email declining an invitation because I’ll be traveling, but make it warm and leave open the possibility of meeting next month.
Producing a good response requires the model to maintain several constraints at once. It needs to recognize that the output should be an email, that the invitation should be declined, that travel is the reason, that the tone should be warm, and that the ending should leave open a future meeting.
All of those requirements influence the predictions.
So yes, the model predicts what comes next.
But the context informing those predictions can be remarkably sophisticated.
Why Doesn’t It Always Pick the Most Likely Word?
If a model always selected the single most probable continuation, its writing could become repetitive and predictable.
Instead, language generation can involve selecting among several plausible possibilities based on their probabilities and the system’s settings.
Imagine the sentence:
She looked out across the ocean and felt…
Possible continuations might include “calm,” “small,” “free,” “nervous,” “peaceful,” or something much more elaborate.
Several choices could make sense.
Allowing some variation helps models produce more natural and creative language.
The amount of variation can also be adjusted. Some configurations make outputs more predictable, while others allow more diversity.
What Is a Parameter?
You’ll often hear that an AI model has billions of parameters.
A parameter is an adjustable numerical value inside the neural network.
During training, the model changes these values to improve its predictions.
One parameter doesn’t correspond neatly to one fact.
There isn’t necessarily a specific parameter that means “Paris is the capital of France” and another that means “cats have whiskers.”
Knowledge and capabilities are generally distributed across complex patterns of parameters.
You can imagine parameters as an enormous collection of tiny settings inside the model.
Training adjusts those settings until the network becomes good at modeling the patterns in its training data.
Does ChatGPT Search a Database for Every Answer?
No.
A language model itself doesn’t normally respond by searching a giant database of prewritten answers and selecting the closest one.
If you ask it to write a story about a penguin opening a bakery on Mars, there probably isn’t an exact story sitting somewhere waiting to be retrieved.
The model can generate a new one by combining learned patterns involving penguins, bakeries, Mars, storytelling, dialogue, humor, and whatever other instructions you provide.
However, AI systems can also be connected to external tools.
An assistant might search the web, retrieve documents, query databases, use a calculator, or access other software when appropriate.
In those cases, the overall AI system is combining language generation with external information.
That’s different from information being stored directly inside the language model.
How Does an LLM “Know” Facts?
During training, language models encounter many examples containing factual relationships.
If text repeatedly describes Tokyo as the capital of Japan, the model can learn a strong relationship among those concepts.
That relationship becomes encoded across the model’s parameters.
Later, when asked for Japan’s capital, “Tokyo” becomes an extremely likely continuation.
But this way of representing knowledge is different from looking up a row in a verified database.
That’s important because it explains one of the biggest weaknesses of language models.
They can sometimes produce false information with exactly the same fluent style they use for true information.
Why Do LLMs Hallucinate?
A language model’s core task is to generate a plausible continuation based on context.
It doesn’t inherently possess a built-in truth detector for every statement it produces.
If the model has strong learned patterns around a question, it may generate an accurate answer.
But if the information is obscure, ambiguous, missing, outdated, or poorly represented in training, the model can still generate language that sounds like an answer.
That can lead to fabricated facts, incorrect dates, nonexistent studies, fake quotations, or invented references.
These errors are commonly called hallucinations.
The model isn’t necessarily “lying” in the human sense. It is generating a continuation that fits learned patterns but doesn’t correspond to reality.
That’s why factual verification remains important.
Why Can LLMs Write in Different Styles?
Suppose you ask for the same explanation three different ways.
Explain photosynthesis like a scientist.
Explain photosynthesis to a six-year-old.
Explain photosynthesis as a funny story.
The underlying topic hasn’t changed, but the expected language patterns have.
Because the model has learned patterns from many different styles of writing, it can adapt its output based on your instructions.
It can change vocabulary, sentence length, tone, structure, formality, and level of detail.
The model isn’t merely retrieving “the photosynthesis answer.”
It’s generating a version suited to the context you’ve provided.
How Can It Remember Earlier Parts of a Conversation?
During a conversation, previous messages can be included as part of the context supplied to the model.
That means when you ask a follow-up question such as:
Can you make that shorter?
the model can see that “that” refers to the previous response.
It uses earlier conversation context when generating the next answer.
However, the amount of information a model can process at once isn’t unlimited. Models have a context window, which defines how much information can be considered within a particular interaction.
Modern systems can have very large context windows, but there is still a limit.
Long-term memory, when an AI product provides it, is a separate system from the language model simply keeping every conversation permanently inside its active context.
How Does an LLM Follow Instructions?
A model trained only to predict text isn’t automatically a helpful assistant.
After initial training, models can go through additional training designed to make them better at following instructions.
They may be shown examples of questions and useful responses. Human evaluators can provide feedback about which answers are more helpful, accurate, safe, or appropriate. Other training methods can then use those signals to improve behavior.
System-level instructions can also influence how the model responds.
These additional stages help turn a general language model into an assistant capable of following requests rather than merely continuing text.
How Can an LLM Generate Computer Code?
Computer code is also a form of structured language.
Programming languages have syntax, patterns, conventions, and relationships just like natural languages do, although their rules are much stricter.
If a model is trained on sufficient code and related material, it can learn patterns associated with functions, variables, APIs, algorithms, debugging, documentation, and different programming languages.
When you ask it to write a Python function, it generates code using those learned patterns.
This doesn’t guarantee that the code will work.
Just as an LLM can generate a grammatically perfect but factually incorrect sentence, it can generate beautifully formatted code containing a subtle bug.
The output still needs to be tested.
How Can LLMs Appear to Reason?
Modern language models can do much more than complete simple sentences. They can compare options, analyze documents, solve certain logical problems, plan steps, write programs, and work through unfamiliar tasks.
Some of these capabilities emerge as models become larger, receive better training, and learn from enormous numbers of examples involving explanations and problem-solving.
Modern AI systems can also allocate more computation to difficult tasks and use external tools to gather information or verify parts of their work.
This can produce behavior that looks much more like reasoning than simple autocomplete.
But it remains important not to assume that human-like output means the underlying process is identical to human thought.
The model’s internal mechanism is fundamentally computational.
Why Do Bigger Models Often Perform Better?
Increasing model size can give a neural network greater capacity to represent complex patterns.
But size alone isn’t enough.
Performance also depends on training data, training methods, model architecture, computational resources, post-training techniques, evaluation, and many other design decisions.
A smaller, well-designed model can outperform a larger model on certain tasks.
Modern AI development therefore isn’t simply a race to create the model with the largest number of parameters.
Researchers increasingly focus on efficiency, reasoning capabilities, multimodal abilities, tool use, data quality, and specialized models as well.
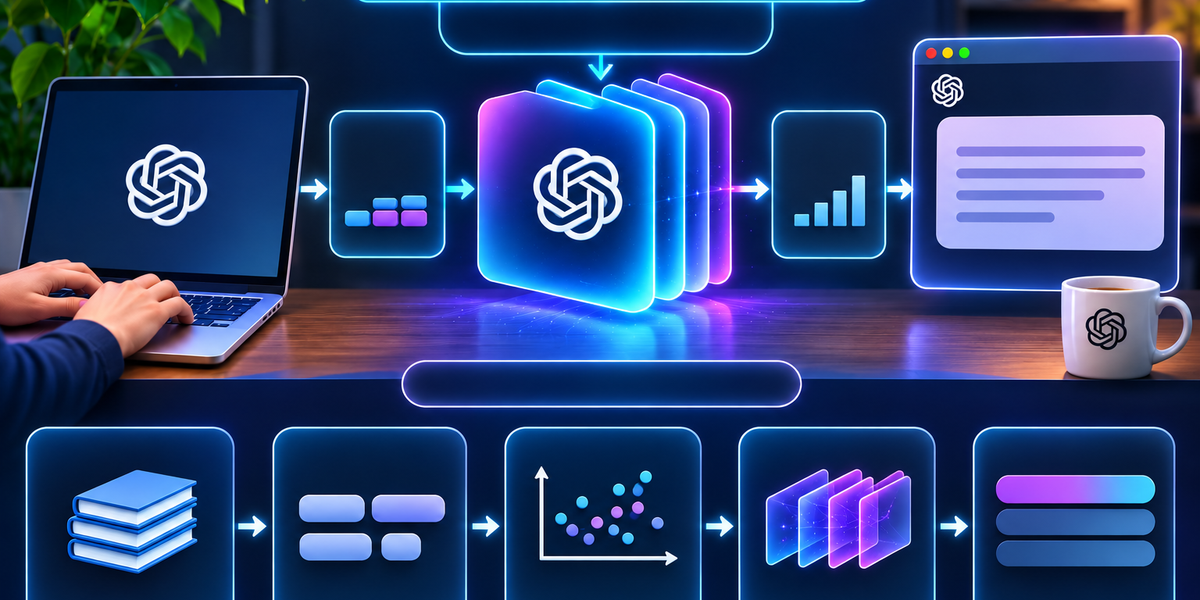
What Happens Between Your Prompt and the Answer?
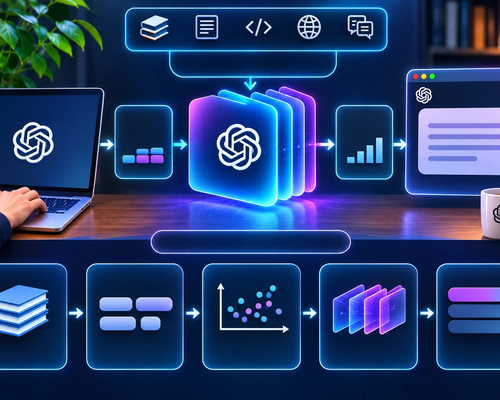
The full process can be summarized fairly simply.
You type a prompt.
The system breaks the text into tokens.
Those tokens are converted into numerical representations.
The model processes those representations through many layers of a neural network.
Attention mechanisms help determine relationships within the available context.
The model calculates probabilities for possible next tokens.
A token is selected.
That token is added to the context.
The process repeats.
Eventually, you receive a complete response.
Behind those few seconds of interaction are enormous amounts of computation and years of research into machine learning, neural networks, language modeling, distributed computing, and AI safety.
The Simple Version
Large language models don’t usually write responses by retrieving entire prewritten answers.
They generate text.
During training, they learn patterns from enormous amounts of data. Those patterns become encoded across a huge network of numerical parameters.
When you provide a prompt, the model processes the context and predicts what token should come next. It then uses that new token to predict the next one, continuing until it has generated a response.
Because the model has learned extremely complex patterns involving language, knowledge, structure, style, and problem-solving, those predictions can produce remarkably sophisticated results.
Sometimes they’re accurate.
Sometimes they’re creative.
Sometimes they’re wrong.
And sometimes the result feels so natural that it’s easy to forget what is happening underneath.
At its core, a large language model is doing something deceptively simple: looking at the context it has and repeatedly predicting what should come next.
The extraordinary part is how much capability can emerge from doing that at enormous scale.